You can turn a long transcript into a summary, action items or meeting minutes on your own Mac, with no per-use credits, by running a language model on the machine. The do-it-yourself version means installing a model runtime, downloading a model of several gigabytes, writing a prompt that does not invent things, and splitting transcripts that are longer than the model can read at once.
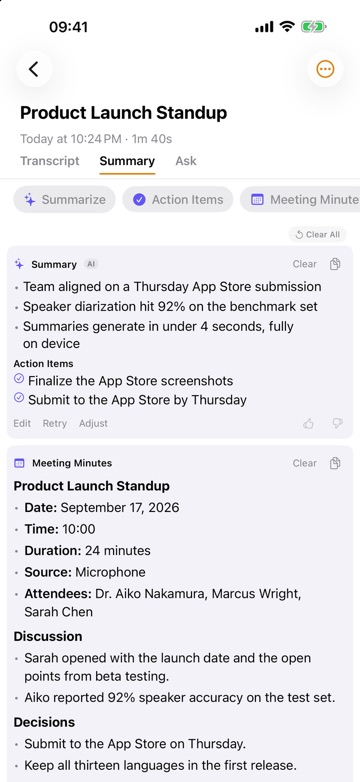
ThinkScribe for Mac does the whole job from the transcript: choose Summarize, Meeting Minutes or Executive Brief, or ask a question about the recording. You choose the AI engine: Apple Intelligence (provided by Apple) or ThinkScribe AI (a one-time download that runs on your device). Your transcripts are never sent to us.
This guide explains how summarizing on your Mac works and what makes the result good or bad, then walks through it in ThinkScribe.
How summarizing on your Mac works
A language model is a large file of learned weights plus a runtime that feeds text through them. For summarizing on a Mac, the runtime loads the weights into memory and uses the Apple silicon GPU to generate the summary one token at a time. Nothing about the transcript has to go anywhere else.
Two numbers decide whether a do-it-yourself setup feels good:
- Memory. A general model in the 7 to 8 billion parameter class, compressed to 4 bits per weight, takes around 5 GB, and a long transcript adds working memory on top. On a 16 GB Mac that is comfortable; on 8 GB, smaller models are the practical choice and miss more details. How much RAM a Mac needs explains the arithmetic.
- Context window. The number of tokens the model can look at in one go. This is the limit most people hit first, and it is covered below.
A prompt that produces useful summaries
Models summarize badly when asked to "summarize this". They do well when told who the summary is for, what shape it should take and what to leave out. A good meeting prompt asks for:
- A two-sentence overview of what the meeting was about.
- Key decisions, with who made them when that is clear.
- Action items in the form "Owner: task (deadline if stated)".
- Open questions that were raised but not resolved.
And it adds three rules: do not invent anything that is not in the transcript, say so when something is missing rather than guessing, and keep names, numbers and dates exactly as they appear.
Change the audience and the list, and the same approach handles other recordings. For a lecture, ask for definitions, the key results and a few questions to answer from memory instead of decisions and action items. Turn a lecture into study notes shows that variant.
The context window problem
Every model has a maximum number of tokens it can read at once, and do-it-yourself runtimes often start models with a short default window. When the transcript is longer, the beginning is dropped without warning, and the summary describes only the end of the meeting.
A rough conversion helps: a minute of conversation is about 150 words, and 150 words is about 200 tokens. A one-hour meeting is therefore around 12,000 tokens before the prompt, and a two-hour workshop will not fit in a generous window.
There are two fixes, used together:
- A larger window. It costs memory and slows the start of the answer, and the model has to support it.
- Map-reduce. Split the transcript into pieces that fit, summarize each piece, then summarize the summaries. The catch is that details dropped from a piece summary are gone for good, which is why the piece prompt has to insist on keeping names, numbers and decisions.
Asking questions instead of summarizing
When you already know what you are looking for, a question beats a summary: "What did we agree about the launch date?" A do-it-yourself setup can answer it, with the same window limits, but it cannot point you to the moment in the audio where it was said. That link back to the recording is what turns an answer into something you can check.
What the DIY route costs you
The upkeep is real: keeping the runtime and model updated, remembering the context setting, keeping a chunking script in step with your transcripts, and copying results into wherever your notes live. It is a fine weekend project for someone who likes the Terminal and a poor fit for someone who wants minutes after every call.
How to summarize a transcript in ThinkScribe
ThinkScribe for Mac runs on a Mac with Apple silicon and macOS 26 or later.
- Record (⌘R) or import a file (⌘I). The transcript is made on your Mac, with speakers told apart.
- Choose the AI engine in Settings > AI Assistant: Apple Intelligence, provided by Apple on Macs that support it, or ThinkScribe AI, a one-time download that runs on your device.
- Press ⇧⌘S or choose Summarize, Meeting Minutes or Executive Brief. The summary includes an Action Items list, and Mind Map gives you a map of the topics.
- Check and refine. Summary points have citations you can click to jump to the line in the transcript. Edit a result or try again if it misses the point.
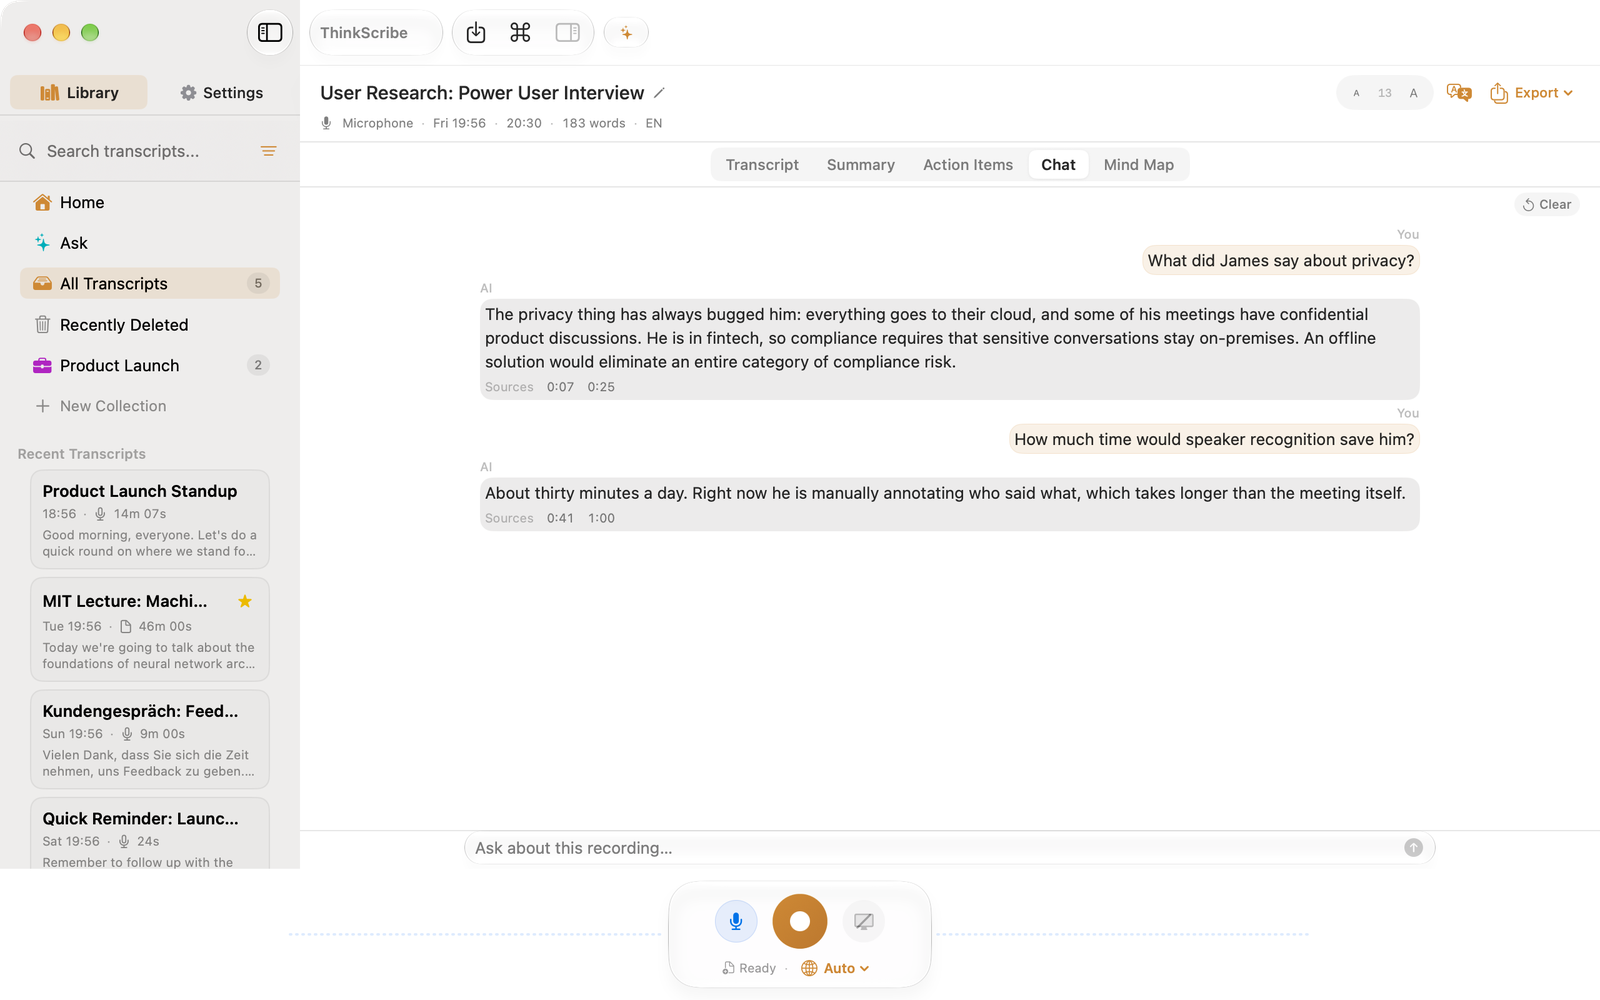
- Ask questions about the recording (⌥⌘C, Chat About This Recording). On the Mac, answers show sources you can click to jump to the moment.
- Export as Markdown, PDF or Word Document, or use Share to Notes to send it to Apple Notes.
On iPhone and iPad, the same summaries and questions sit next to the transcript. Meeting minutes and action items from a recording goes deeper, and the meeting transcription page shows the whole flow.
DIY next to ThinkScribe
| DIY on your Mac | ThinkScribe for Mac | |
|---|---|---|
| Setup | Runtime, model download, prompt, chunking script | Pick an AI engine in Settings |
| Formats | Whatever your prompt asks for | Summary, Meeting Minutes, Executive Brief, Mind Map, Action Items |
| Link back to the audio | None | Citations that jump to the line |
| Where transcripts go | Nowhere, if everything runs on the Mac | Never sent to us |
For the full picture of recording, transcribing and summarizing across your devices, see the complete guide to voice to text.
Frequently asked questions
Can I summarize a transcript on my Mac without internet?
Yes, with a model that runs on the Mac. In ThinkScribe, choose ThinkScribe AI in Settings > AI Assistant: after its one-time download it runs on your device and works offline. Apple Intelligence is the other option, provided by Apple on Macs that support it.
Which AI engine should I pick in ThinkScribe?
Apple Intelligence, provided by Apple, is an option on Macs that support it. ThinkScribe AI is a one-time download that runs on your device, and it is the choice when your Mac does not offer Apple Intelligence or you prefer that route. Try both on the same meeting and keep the one whose summaries you prefer.
How long a transcript can a language model summarize?
In a single pass, as long as its context window allows: at around 200 tokens per minute of speech, a 16,000-token window holds roughly an hour of conversation plus the prompt. Beyond that the transcript has to be split and summarized in stages, which is what a map-reduce approach does.
Is a summary made on the Mac as good as a cloud one?
For meeting summaries and action items, a good model on a recent Mac is close enough that most people will not notice a difference. The largest cloud models still have an edge on very long documents, subtle reasoning and rare languages. For the routine job of turning a call into notes, a model on your Mac does it well.
Can I ask questions about a meeting instead of reading the summary?
Yes. Ask a question about the recording, for example, "What decisions were made?" On the Mac, answers show sources you can click to jump to that moment. To ask across several meetings, put them in a collection and ask the collection.