Speaker diarization answers "who spoke when". On a Mac without a cloud service it takes two models working together: a speech recognizer for the words and a diarization pipeline for the voices, plus a step that lines the two up. Open-source toolkits can do this in Python, with gated model downloads, an access token and an alignment script you write yourself.
Or you can let the app do it. ThinkScribe separates speakers on your device when a recording stops, labels them Speaker 1, Speaker 2 and so on, and remembers the names you give them for future recordings. This guide explains how diarization works and what gets in its way, then shows how to get named speakers in ThinkScribe on a Mac, iPhone or iPad.
What diarization produces
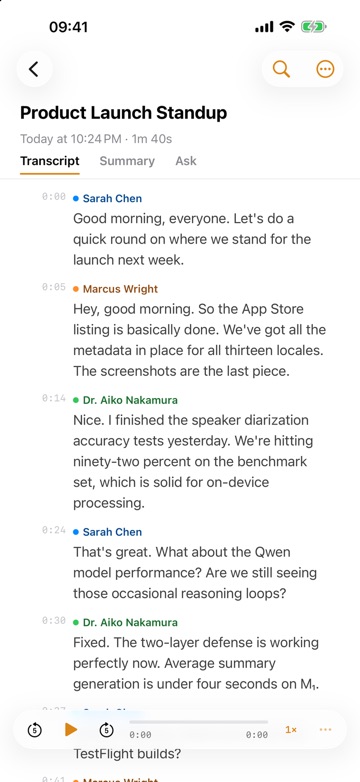
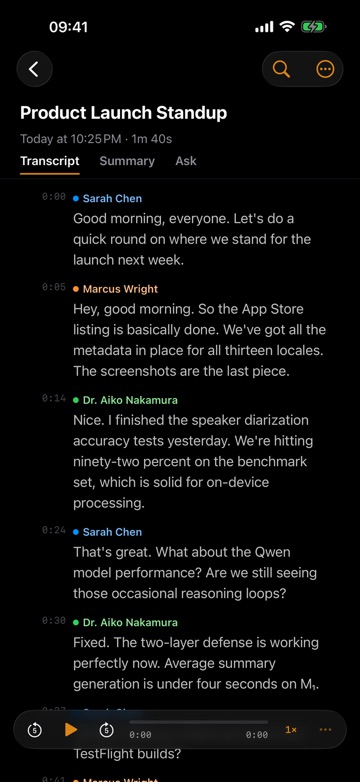
The raw output of diarization is a list of time ranges, each tagged with an anonymous label. Joined with a transcript it becomes a script you can read:
[00:00:02] Speaker 1: Thanks for joining. Let's start with the budget.
[00:00:09] Speaker 2: Sure. The numbers moved since last week.
That difference, between a wall of text and a conversation, is what makes interviews, meetings and panels usable afterwards. Summaries get better too, because decisions can be attributed to a person.
How it works, in three steps
Most current diarization systems share the same design, which the speaker diarization explainer covers in more depth:
- Segmentation. A small neural network scans the audio in short windows and marks where speech is, where the speaker changes, and where two people overlap. This doubles as voice activity detection.
- Embeddings. Each stretch of speech is turned into a fixed-length vector, a kind of voice fingerprint that captures how someone sounds rather than what they say.
- Clustering. Similar fingerprints are grouped, and each group becomes one speaker label. Knowing roughly how many people spoke makes this step much more reliable.
The speech recognizer is a separate model with its own timestamps. To get "Speaker 2 said this sentence", something has to assign each piece of transcript to the speaker whose turn overlaps it most. Doing that per segment is simple but blurs a speaker change in the middle of a long segment; doing it per word is more precise and needs word-level timings.
What doing it yourself involves
Hand-built local diarization on a Mac is a real project, not a download:
- A Python environment with a machine learning framework, audio decoding libraries and their matching versions. Version mismatches between these are the most common source of cryptic errors.
- Gated model weights. Popular diarization models require you to accept terms on a model hub and use an access token for the first download.
- Apple silicon gaps. Some toolkits do not use the Mac's GPU, so recognition falls back to the CPU, and long recordings take a long time with the larger models.
- Alignment code. You write the overlap logic that joins speaker turns to transcript lines, and handle segments that span a speaker change.
- Upkeep. Command-line options, default models and install steps change between releases.
Rough expectations for one hour of audio on an Apple silicon Mac: diarization alone takes from under a minute to tens of minutes depending on the tool and hardware path, and recognition with a large model on the CPU can take longer than the meeting itself.
Anonymous labels are not names
A diarization pipeline never knows who "Speaker 1" is. Turning labels into names needs enrollment: store a voice fingerprint for a known person, then compare each new speaker against the stored ones. Toolkits expose the fingerprints, but the matching logic, the thresholds and the database are yours to build. This is the part that makes the difference between labels you fix every time and names that simply appear.
How to get speaker labels and names in ThinkScribe
ThinkScribe runs on iPhone and iPad with iOS or iPadOS 26 or later, and on a Mac with Apple silicon and macOS 26 or later.
- Record, or bring in a file: Import File... (⌘I) on the Mac, or Import Audio File on iPhone and iPad.
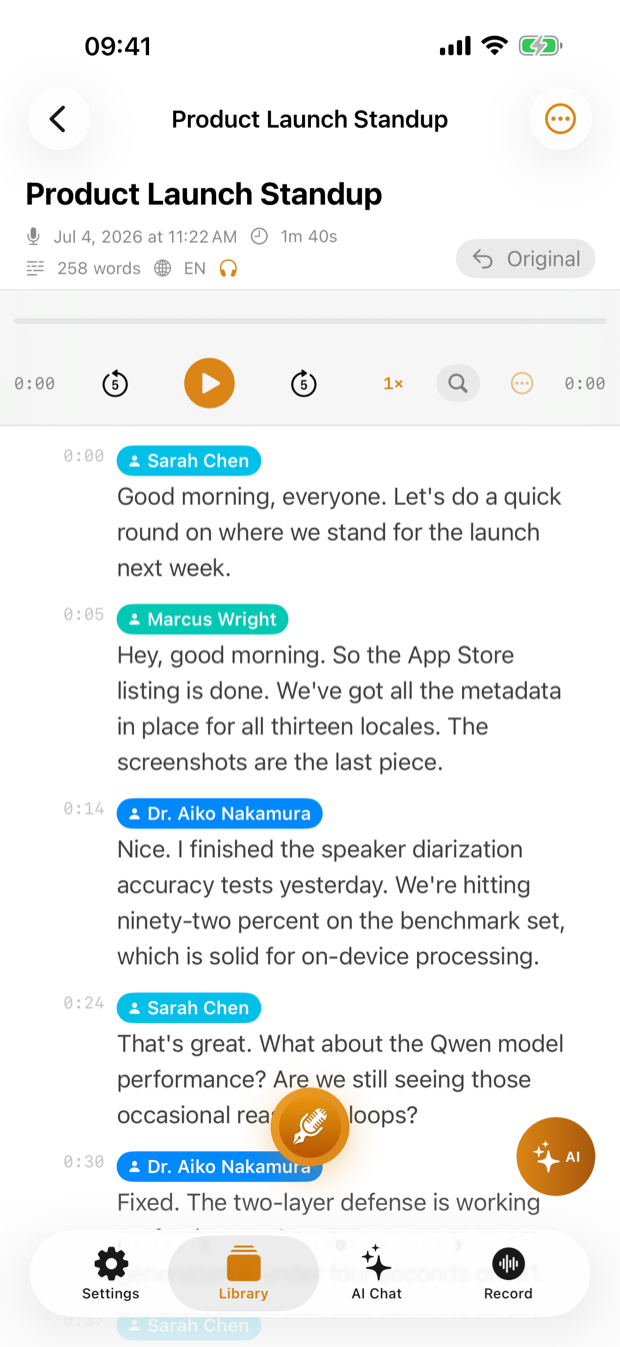
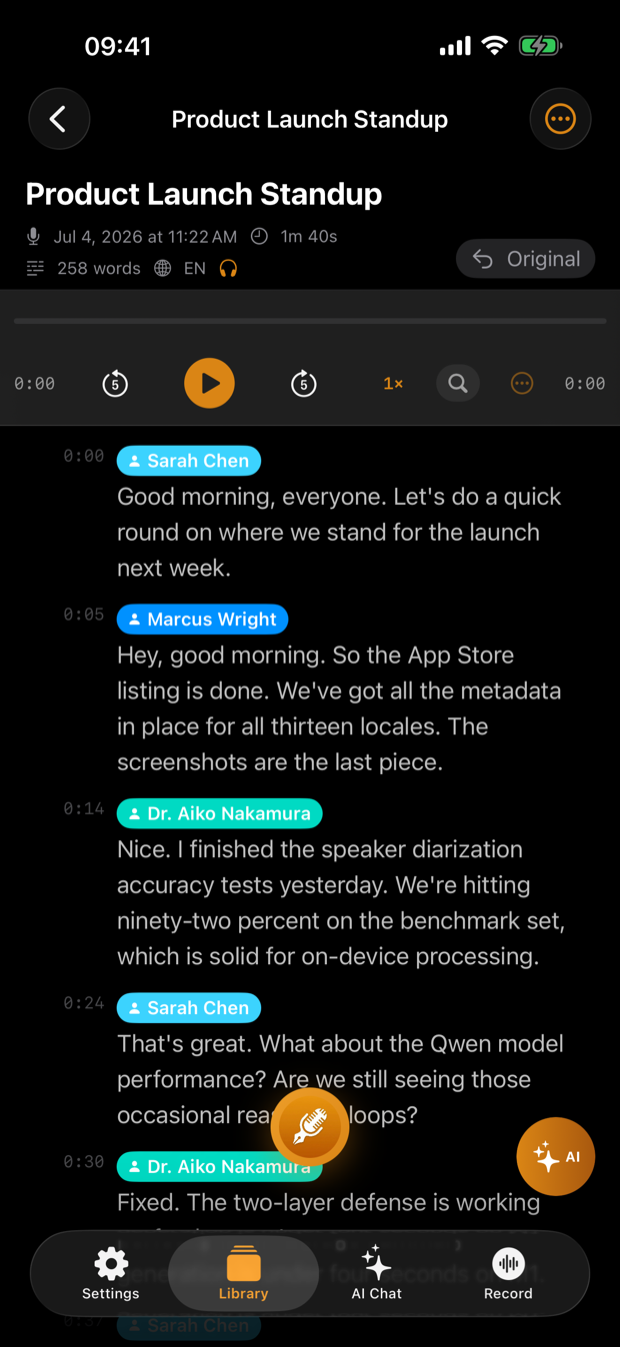
- Stop the recording. The transcript is made on your device ("Transcribing...", then "Identifying speakers..."), and speakers are separated automatically as Speaker 1, Speaker 2 and so on. You do not need to tell it how many people spoke.
- Name a speaker: long-press the speaker badge in the transcript and choose Rename Speaker.... Pick someone from Known Speakers or type a name, and every line with that label updates.
- In new recordings, saved voices are recognized automatically. When ThinkScribe is not sure, it shows Possible matches for you to Confirm or Reject.
- Manage voices in one place: on iPhone, Settings > Speaker Identification > Manage Known Speakers; on the Mac, Settings > AI & Models > Known Speakers > Manage.... There you can Add Speaker from 20 to 30 seconds of recorded or imported voice, rename, merge two entries for the same person, or delete one.
For harder recordings, ThinkScribe downloads a better speaker model once, on its own; until it is ready, the standard model is used. Live speaker labels while you record are available as a setting on the Mac and on iPhones with 8 GB of memory, off by default. Speaker identification in ThinkScribe walks through naming in more detail.
Getting better labels, whatever tool you use
- Microphone distance. A laptop mic three meters from everyone produces voice fingerprints that blur together. Putting the phone or mic closer to the people talking changes the result more than any setting.
- Overlap. Crosstalk is where every system loses the most accuracy. Expect a quick interruption to be missed or given to the wrong person.
- Similar voices. Two speakers of the same age, sex and accent are the hardest case. Naming both once gives the recognizer a reference for each.
- Phone and video calls. Compressed call audio still separates two or three speakers well. If one person shows up as two labels, rename both to the same name, or merge them in Known Speakers.
- Long silences and music. Intros, hold music and background TV can create an extra speaker. Rename or ignore it rather than fighting it.
Diarization is the difference between a transcript and a usable record for interview transcription, and journalists will find more on the workflow in interview transcription for journalists. If the recordings are meetings, the meeting notes pipeline shows what to do with a labeled transcript, and the complete guide to voice to text covers everything else.
Frequently asked questions
Can I get speaker labels on a Mac without uploading the audio?
Yes. ThinkScribe separates speakers on your device after the recording stops, and it works offline. There is no account, and your recordings and transcripts are never sent to us.
How accurate is local speaker diarization?
On clean recordings with two or three speakers, labels are right for most of the transcript, and errors cluster at turn changes and where people talk over each other. Published benchmarks show error rates ranging from the low teens on meeting recordings to well above that on far-field and crosstalk-heavy audio, so noisy recordings deserve a quick check.
Can I get real names instead of Speaker 1 and Speaker 2?
Yes. In ThinkScribe, long-press a speaker badge, choose Rename Speaker..., and pick or type a name. Every line with that label updates, and the named voice is recognized automatically in new recordings.
Do I need to tell ThinkScribe how many people are speaking?
No. The number of speakers is detected automatically. If one person ends up split into two labels, give both the same name or merge them in Known Speakers.
Does speaker recognition work on iPhone as well as the Mac?
Yes. Speaker labels, renaming and Known Speakers work on iPhone, iPad and Mac. With iCloud Sync turned on, speaker profiles sync between your devices through your own iCloud account, provided by Apple.