

Yes, you can run OpenAI's Whisper speech model locally on a Mac. On Apple silicon it runs offline once the model file is on your disk, and the audio never has to go to a transcription service. Doing it yourself, though, is a small software project: you choose a runtime and a model size, convert your audio into the format the model expects, learn the options that control language and output, and keep all of it working as versions change.
Most people who search for this want the result rather than the project: an accurate transcript made on their own Mac. This page explains what Whisper is, what running it yourself involves, which problems you will meet and why, and then the one-step way in ThinkScribe.
If you are still deciding which speech model family to use at all, Whisper vs Parakeet compares the two most common open ones in plain words.
What Whisper is
Whisper is an open speech recognition model that OpenAI released in 2022. It was trained on a very large amount of audio from the web paired with text, and it comes in a family of sizes, from tiny up to large-v3, plus a large-v3-turbo variant that keeps the large encoder and shrinks the decoder for speed.
It works in two halves. An encoder listens to a 30-second window of audio and turns it into a compact representation. A decoder then writes the transcript one piece of text at a time, looking both at the audio and at what it has already written. That design gives Whisper fluent, well-punctuated text and a wide language range (roughly a hundred languages, with accuracy that falls off sharply for the ones with little training data). It is also the source of its best-known weakness: over silence or music, the decoder sometimes writes sentences nobody said.
What running it yourself involves
Whisper is a set of model weights, not an app. To turn a recording into text on your Mac you assemble the rest yourself. Here is the honest shape of it.
A runtime. The model needs a program to run it. The usual choice on a Mac is a community command-line port such as whisper.cpp, installed through a developer package manager, or a Python environment with the reference code. Either way you work in Terminal, and the name of the program, its options and its install method change between versions.
A model file. You download one size of the model, from a few hundred megabytes for the small ones to around three gigabytes for the largest, and keep track of where it lives. Some ports also want a second, converted copy of the model to use Apple's machine-learning hardware, which means another build step and a first run that compiles the model for your chip.
Audio conversion. Many runtimes read only one kind of file: 16 kHz, mono, uncompressed WAV. Your recordings are probably M4A, MP3 or video, so every file goes through a converter first. A WAV saved by another app is usually 44.1 kHz stereo and fails in the same way.
Options. You set the language (some ports default to English if you forget), choose output formats (plain text, SRT or VTT subtitles, JSON), and name the output files. Batch jobs mean writing a small shell loop.
Upkeep. Any macOS upgrade, package update or model release can rename a program, move a download link or change an option. None of it is hard for a developer, but it tends to break on the day you have a recording to deliver.
What you still do not have. At the end you have text files. Speaker labels, a searchable library of past recordings, playback that follows the transcript, summaries and exports to PDF or Word are each a separate project on top.
Choosing a model size
If you do go the manual route, the model size is the main decision, and the trade-off is the same everywhere: bigger is more accurate and slower.
| Size | Good for |
|---|---|
tiny, base |
Testing a setup, quick drafts of clean audio |
small |
Everyday use when speed matters |
medium |
Better on accents and background noise, slower |
large-v3 |
Best accuracy, largest download, slowest |
large-v3-turbo |
Most of large's accuracy with a much faster decoder |
Variants marked .en are English-only and slightly more accurate for English at the same size. Quantized variants are smaller and faster at a small cost in accuracy. The step from base to small is bigger than the step from medium to large.
Memory, speed and Apple silicon
Memory. The model has to fit in memory next to everything else you have open. On an 8 GB Mac, stay with small or a quantized medium. On 16 GB and above, large-v3 runs comfortably. How much memory a Mac needs for local transcription goes into the numbers.
Speed. On an M-series Mac, small transcribes an hour of audio in a few minutes. large-v3 can approach real time on a base M1 and is several times faster on Pro and Max chips; large-v3-turbo is the usual compromise. The first run of any setup is slower because the model loads and, on some ports, compiles for your chip.
Intel Macs run it on the CPU only. Small models work; large ones are slow.
Problems you will meet, and why they happen
Invented sentences over silence, or a sentence that repeats. Whisper's decoder is partly a language model, so when a window holds no speech it can write the most likely text anyway ("Thank you for watching" is a classic), and a bad sentence can become the context for the next window. Why Whisper hallucinates and repeats itself explains the mechanism.
The wrong language. Automatic detection looks only at the opening seconds. A file that starts with music or a different speaker gets decoded in the wrong language from start to finish. Setting the language explicitly avoids it.
Misspelled names and jargon. The model writes the most likely spelling it has seen. Your colleague's surname and your product names are rarely in its training data.
Rough timestamps. Whisper places segment times as part of the text it writes. They are fine for sentence-level subtitles and approximate at word level.
No speakers. Whisper writes one stream of text. Telling who said what is a separate step called diarization.
How to transcribe audio on a Mac in ThinkScribe
If what you want from Whisper is the transcript, ThinkScribe gets you there without the setup. It sets up the speech model for you: nothing to install or convert, and no Terminal.
- Install ThinkScribe for Mac (Apple silicon, macOS 26 or later) and go through the short welcome. It asks for the microphone, and for System Audio if you want to record calls or other apps.
- Choose the spoken language in Settings > Language. There are 28 languages; picking the one that is spoken avoids wrong-language transcripts.
- Bring in the recording with Import File... (⌘I), by dragging it onto the window, or with Open With. MP3, M4A, WAV, AIFF, FLAC, MP4, MOV, OGG, Opus, CAF and AAC all work as they are, and so do WMA, WebM, MKV, AVI, AMR and more.
- Or record directly: New Recording (⌘R) for your microphone, Record System Audio (⇧⌘R) for a call or video.
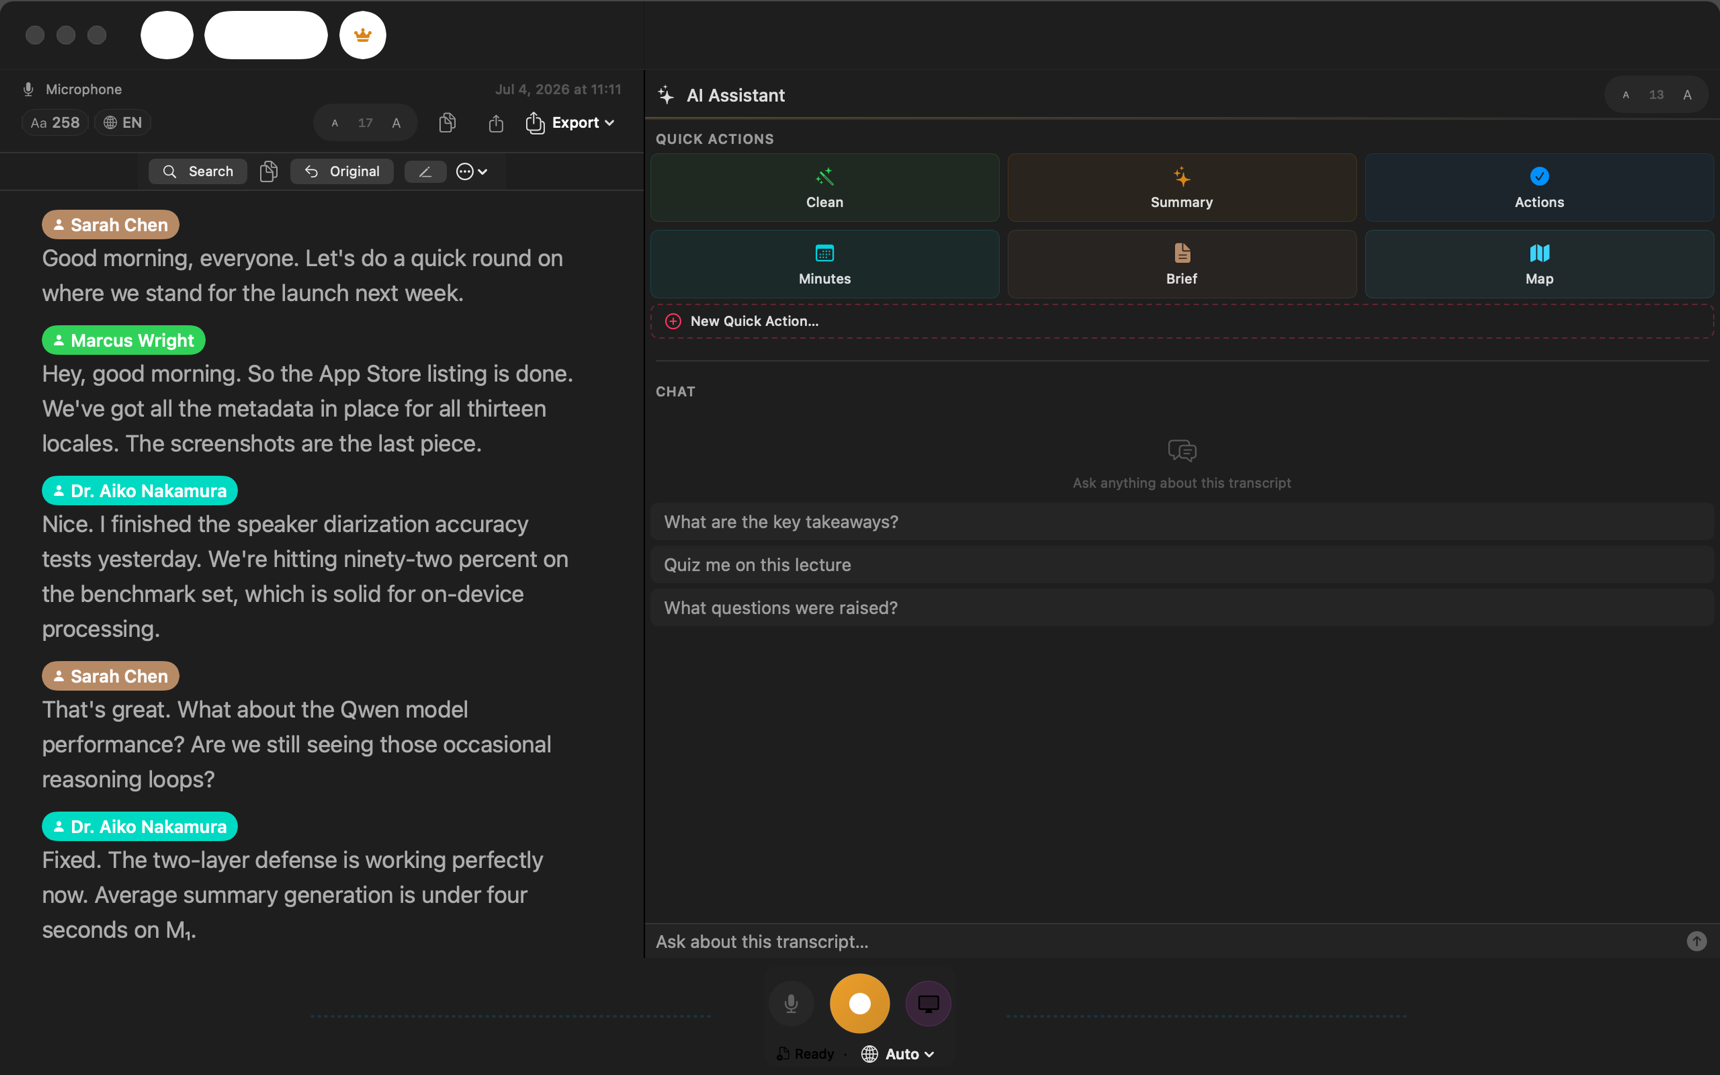
- Read the transcript in the workspace. Speakers are separated automatically as Speaker 1, Speaker 2 and so on; rename one once and ThinkScribe recognizes that voice in new recordings.
- Export it as Plain Text, SRT Subtitles, VTT Subtitles, JSON, Markdown, PDF, Word Document or CSV.
Transcription happens on your Mac and works offline. There is no account, and your recordings and transcripts are never sent to us. The audio to text guide for Mac and importing audio and video files cover the same flow in more detail.
What you get beyond a text file
The part a manual setup leaves out is what happens after the text exists.
- Names and jargon. Add them in Settings > Vocabulary. Words you correct three or more times in transcripts are added for you.
- A library you can search. Every transcript and title is searchable, so an old recording is a search away instead of a folder of
.txtfiles. - The point of the recording. The workspace has Transcript, Summary, Action Items, Chat and Mind Map tabs, so a meeting becomes minutes and a lecture becomes notes.
- Batches. Import several files at once and turn on Auto-Export After Transcription to get the files you need without clicking through each one.
For the bigger picture, including iPhone and voice typing, see voice to text on iPhone, iPad and Mac or the audio to text use case.
How to judge the result, whichever way you go
Test with ten minutes of your own audio, not a benchmark clip. Check four places against the recording: names and numbers, the first and last minute, long pauses (where invented text shows up), and crosstalk.
Frequently asked questions
Can you run Whisper offline on a Mac?
Yes. Once the model file is downloaded, a local Whisper setup needs no network connection, and the audio stays on your Mac. The work is in the setup: a runtime, a model file, audio conversion and command-line options. If you only need the transcript, ThinkScribe transcribes on your Mac and works offline with nothing to set up.
Which Whisper model size should I use on a Mac?
Start with small for a fast, decent result and move to large-v3-turbo when accuracy matters or the audio is noisy. Use the .en variants for English-only material. On an 8 GB Mac, stay with small or a quantized model, because the model has to share memory with everything else you have open.
Do I need Terminal to transcribe audio on a Mac?
Not if you use an app that handles the model for you. In ThinkScribe you import a file with ⌘I or drag it onto the window, pick the language, and the transcript appears with speakers separated. There are no commands, model files or audio conversion steps.
Why does my local Whisper transcript repeat sentences or add text nobody said?
Whisper's decoder writes text partly from what it has already written, so over silence or music it can produce plausible phrases, and one bad window can feed the next. Setting the language explicitly and keeping silence out of the input help. Whatever tool you use, check the transcript around long pauses before you rely on it.
Does ThinkScribe work without an internet connection?
Yes, transcription happens on your Mac, iPhone or iPad and works offline. There is no account, and your recordings and transcripts are never sent to us. Optional features provided by Apple, such as iCloud sync and Apple's Translation, follow Apple's own rules.

